

Using the Gemini Logical Simulator
In this tutorial, we show how you can use the simulator for QuEra’s Gemini logical device. We show how you can define a logical program, compile it for execution, and simulate the results.
# Builtinsimport mathfrom collections import Counter
# Typesfrom typing import Any
import numpy as npfrom bloqade import squin, types
# Functions and methodsfrom bloqade.decoders import BpLsdDecoder
# Gemini Simulator Devicefrom bloqade.gemini import GeminiLogicalSimulator
# Dialectsfrom bloqade.gemini import logicalfrom kirin.dialects import ilistfrom kirin.ir.method import Method
import matplotlib.pyplot as plt
def render_steane_code_qubit(ax:plt.Axes | None = None,center:tuple[float,float]=(0,0))->plt.Axes: if ax is None: _fig,ax = plt.subplots() ax.set_aspect("equal") ax.set_xlim([-2+center[0],2+center[0]]) ax.set_ylim([-2+center[1],2+center[1]]) ax.axis("off") RED = "#EF2F55" PURPLE = "#670EFF" GREEN = "#57BC13"
pos_center = np.zeros([2,7]) pos_center[:,1::] = np.array([np.cos(np.linspace(0,2*np.pi,7)[0:6])*1.5,1.5*np.sin(np.linspace(0,2*np.pi,7)[0:6])]) pos_center += np.array(center).reshape(2,1)
ax.scatter(pos_center[0],pos_center[1],color="w",s=800,zorder=100,edgecolors="k") indexing = [2,0,3,6,4,5,1] for xi, yi, label in zip(pos_center[0],pos_center[1],indexing): ax.text(xi,yi,str(label),ha="center",va="center",zorder=200)
ax.fill([pos_center[0,x] for x in [0,2,3,4]],[pos_center[1,x] for x in [0,2,3,4]],color=RED) ax.fill([pos_center[0,x] for x in [0,4,5,6]],[pos_center[1,x] for x in [0,4,5,6]],color=GREEN) ax.fill([pos_center[0,x] for x in [0,6,1,2]],[pos_center[1,x] for x in [0,6,1,2]],color=PURPLE) logical_label = [indexing.index(5), indexing.index(1), indexing.index(0)] ax.plot(pos_center[0,logical_label],pos_center[1,logical_label],color="k",ls="-",linewidth=5,zorder=50)
return ax
# A minimal kernel that prepares a single qubit in an arbitrary state,# so that it can be shown by the tsim renderer.@logical.kernel(aggressive_unroll=True)def main(): reg = squin.qalloc(1) squin.u3(0.1,0.2,0.3,reg[0]) return logical.terminal_measure(reg)task = GeminiLogicalSimulator().task(main)Some prototype stdutils functions: detectors and observables
Section titled “Some prototype stdutils functions: detectors and observables”We break abstraction a bit between physical and logical qubits. Each logical measurement is a batch of 7 physical measurements as indexed by the following diagram.
In order to correct the errors from a Steane code, we need to inform the decoder and detector error model of the decoding steps. This can be done by defining the detectors and the observables.
For the Steane code, the detectors are four-qubit parity patches corresponding to the three plaquettes of the code; in the following render the default detectors are the red/green/purple patches.
For the Steane code, the obsevables are three-qubit parity lines corresponding to edges of the code; in the following render the default observable is the black line.
render_steane_code_qubit()task.noiseless_tsim_circuit.diagram(width=400)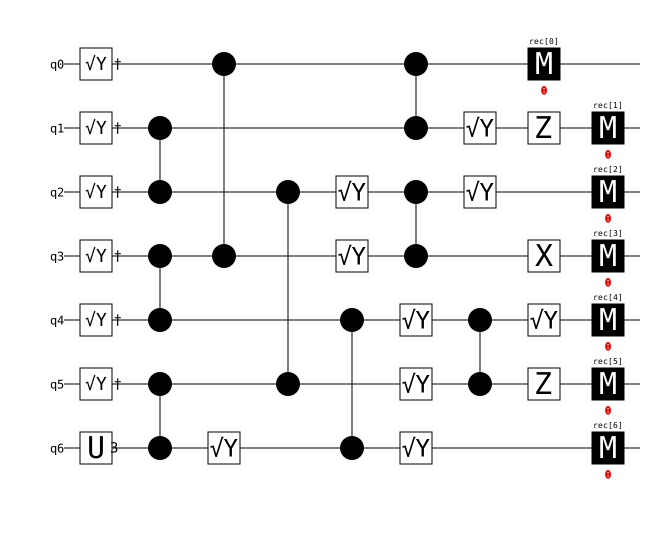
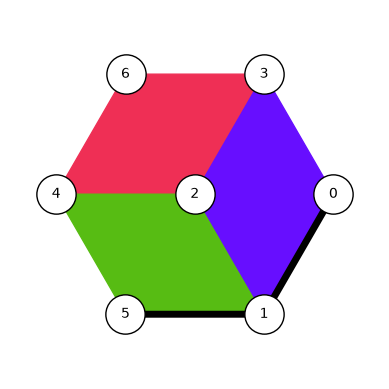
Lets define some default functions which use the squin.set_detector and squin.set_observable functions, which annotate the program for later analysis to generate the detector error model.
For the purposes of our demonstration, lets prepare a simple GHZ state. Note that the decorator is @logical.kernel instead of @squin.kernel.
@logical.kernel(aggressive_unroll=True, verify=True)def main():    reg = squin.qalloc(3)    squin.h(reg[0])    squin.cx(reg[0], reg[1])
    return logical.default_post_processing(reg) # Return the physical measurements
task = GeminiLogicalSimulator().task(main)
The task has several attributes. The key attributes are:
| Attribute | Description |
|---|---|
task.run | Run the task, sampling bitstrings from the noisy distribution |
task.noiseless_tsim_circuit | The underlying physical circuit without noise |
task.tsim_circuit | The underlying physical circuit including noise |
task.detector_error_model | The DEM associated with the noisy circuit |
task.visualize | Render an interactive atom move. |
Rendering of the noiseless circuit:
Section titled “Rendering of the noiseless circuit:”task.noiseless_tsim_circuit.diagram(height=task.noiseless_tsim_circuit.num_qubits*25)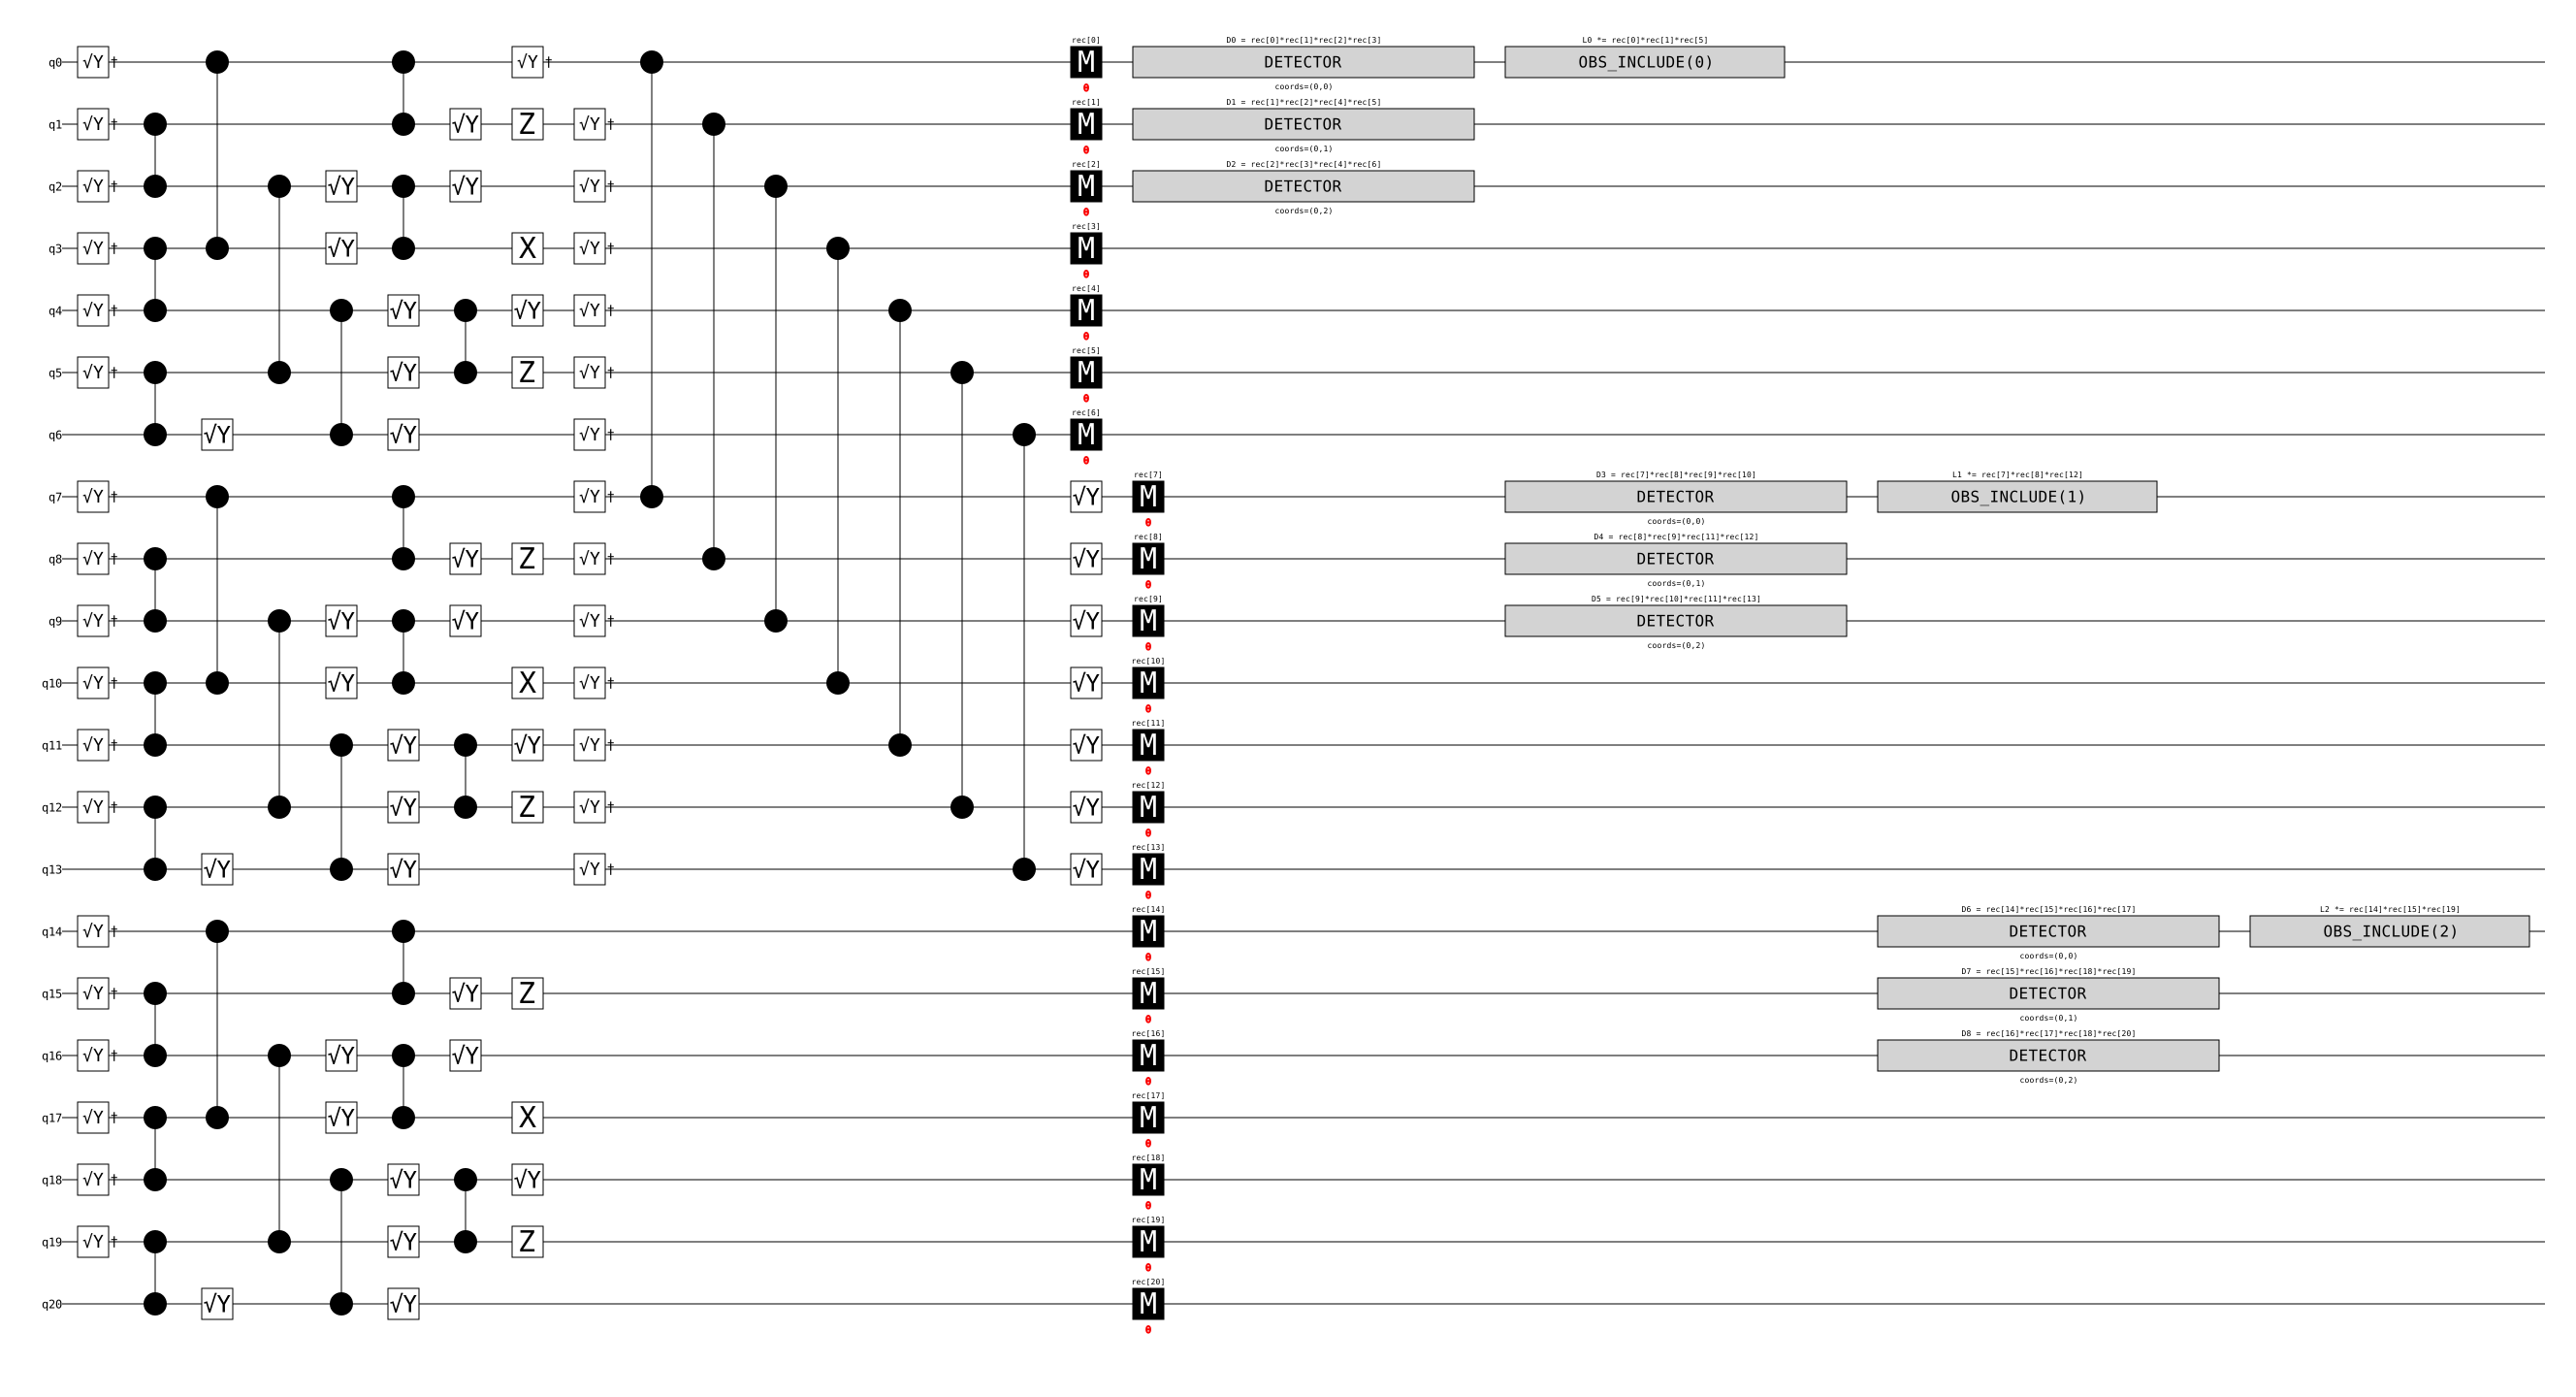
Rendering of the noisy circuit:
Section titled “Rendering of the noisy circuit:”Includes 1 and 2 qubit gate error, spectator errors, and move errors.
task.tsim_circuit.diagram(height=task.tsim_circuit.num_qubits*25)
Running the task
Section titled “Running the task”The task.run attribute compiles the task to tsim and then samples from it. Note that the majority of the time is spent compiling the task; the sampler is very fast.
result = task.run(1, with_noise=True)result_wo_noise = task.run(1, with_noise=False)# After recompilation, the task runs very quickly.result = task.run(10000, with_noise=True)result_wo_noise = task.run(10000, with_noise=False)The result object has several meaningful attributes that are useful for analysis:
| Attribute | Description |
|---|---|
result.return_values | The values returned from the kernel |
result.detectors | The parity values of the annotated detectors |
result.observables | The parity values of the annotated observables |
result.measurements | The physical qubit measurements |
For each value, the zeroth dimension is the shot index.
detectorsare a flattened list of[ [detectors of qubit 0 ], [detectors of qubit 1] [ ... ] ]observablesare a list of[ obsevable of qubit 0, observable of qubit 1, ... ]measurementsis a nested list of[[7 physical measurements of qubit 0], [7 physical measurements of qubit 1], ...]
Indexing is in the same ordering of however the qubits were measured in the logical.terminal_measure statement.
return_values = result.return_valuesdetectors = np.asarray(result.detectors)observables = np.asarray(result.observables)physical = np.asarray(result.measurements)observables_without_noise = np.asarray(result_wo_noise.observables)
print(detectors.shape)print(observables.shape)print(physical.shape)
(10000, 9)(10000, 3)(10000, 21)Decoding and post-selection
Section titled “Decoding and post-selection”Decoders can be inherited from elsewhere but follow a common pattern. Given the detector error model, flips to the logical qubits can be decoded based on the detector triggers. Because the code is linear, the corrected code is simply the XOR of the flips and the observables.
Alternatively, one may postselect on having no errors, or all detectors being zero.
# Correctflips = BpLsdDecoder(task.detector_error_model).decode(detectors)observables_corrected = observables ^ flipsprint("Average bits flipped:", np.average(flips))
# Postselectpost_selection = np.all(detectors == 0, axis=1)observables_postselected = observables[post_selection, :]print("Postselection rate:  ", len(observables_postselected) / len(observables))
Average bits flipped: 0.13993333333333333Postselection rate: 0.6132Analysis 1: parity
Section titled “Analysis 1: parity”For the GHZ state, we have the convenience of the final state being uniformly sampled from 00 or 11, with 01 or 10 indicating an error outside of the distribution. Thus, computing the parity of the observables can serve as a proxy of the fidelity of the distribution: parity 0 means no error, parity 1 means error, and the average parity is the error rate. Postselection and correction decreases the parity, meaning the final error is better!
print("Average parity (before correction):", np.average(observables[:,0] ^ observables[:,1]))print("Average parity (after correction):", np.average(observables_corrected[:,0] ^ observables_corrected[:,1]))print("Average parity (after postselection):", np.average(observables_postselected[:,0] ^ observables_postselected[:,1]))Average parity (before correction): 0.0978Average parity (after correction): 0.0789Average parity (after postselection): 0.002446183953033268Some helper functions and standard utilities to analyze statistical divergence
Section titled “Some helper functions and standard utilities to analyze statistical divergence”# helper functions to analyze statistical distribution of logical measurementsdef get_hist(obs_array: np.ndarray): return Counter(tuple(map(int, x)) for x in obs_array[:])
def kl_divergence(p_hist: Counter, q_hist: Counter) -> float: """Compute the KL divergence D_KL(P || Q) between two histograms.""" total_p = sum(p_hist.values()) total_q = sum(q_hist.values()) if total_p == 0 or total_q == 0: return float("inf") # Infinite divergence if one distribution is empty divergence = 0.0 for key in p_hist: p_prob = p_hist[key] / total_p q_prob = q_hist.get(key, 0) / total_q if q_prob > 0: divergence += p_prob * math.log(p_prob / q_prob) else: divergence += p_prob * math.log(p_prob / (1e-10)) # Avoid log(0) return divergenceThe Kullback-Leibler divergence measures the dissimilarity between two probability distributions. When the KL divergence is zero, there is no loss when the noisy distribution (Q) is used to represent the perfect distribution (P). Similar to the parity measurement above, we find that the divergence is lower for corrected and postselected distributions. Note that the distribution is approximated from finite sampling (a simple frequentist bootstrap) so the KL divergence is an upper bound on the true distribution (in expectation).
observables_hist = get_hist(observables)observables_decoded_hist = get_hist(observables_corrected)observables_postselected_hist = get_hist(observables_postselected)observables_wo_noise_hist = get_hist(observables_without_noise)
# compute and print the KL divergence between the histogramsprint("KL divergence between noiseless and raw observables:",kl_divergence(observables_wo_noise_hist, observables_hist))print("KL divergence between noiseless and decoded observables:",kl_divergence(observables_wo_noise_hist, observables_decoded_hist))print("KL divergence between noiseless and post-selected observables:",kl_divergence(observables_wo_noise_hist, observables_postselected_hist))
KL divergence between noiseless and raw observables: 0.16064702697682368KL divergence between noiseless and decoded observables: 0.13049818616321002KL divergence between noiseless and post-selected observables: 0.005560317168367126Dos and do nots for kernels
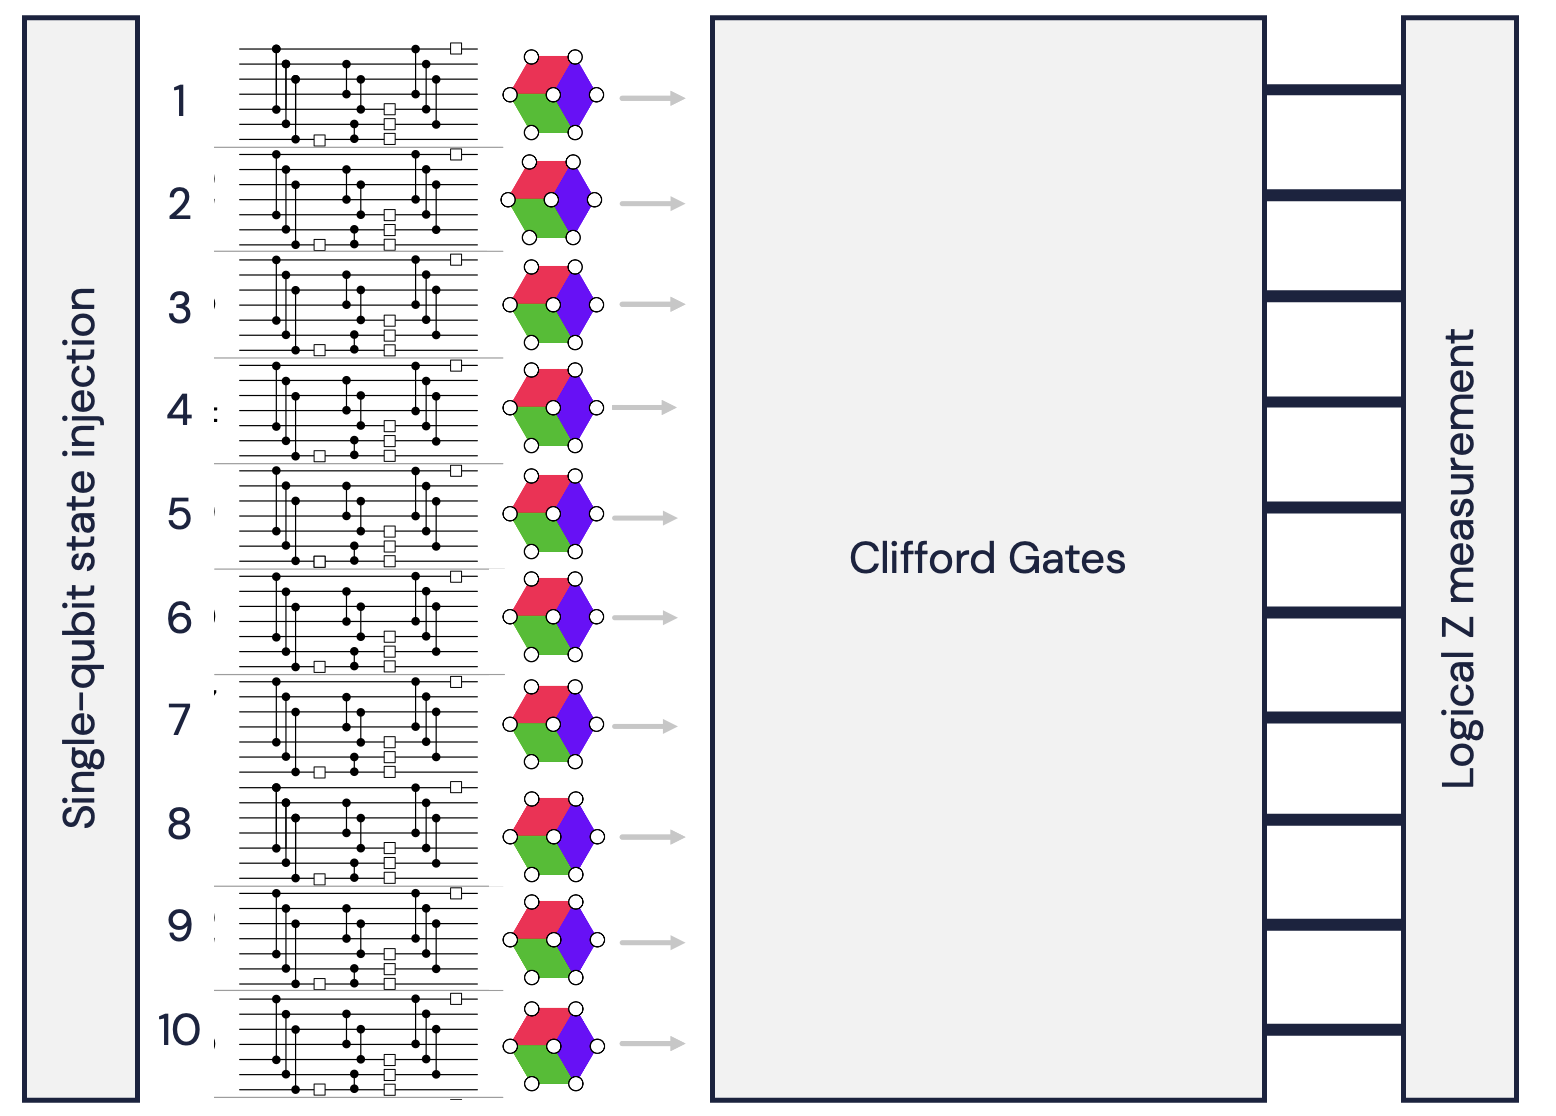
Section titled “Dos and do nots for kernels”A valid kernel for Gemini must:
- Have less than 10 qubits
- Only have a single non-Clifford gate per qubit, acting as a single-qubit gate as the first gate on each qubit
- Measurement is in Z basis only.
Too many qubits
try:    @logical.kernel(aggressive_unroll=True, verify=True)    def main():        reg = squin.qalloc(12)        squin.h(reg[0])        squin.cx(reg[0], reg[1])
        return logical.default_post_processing(reg)
    task = GeminiLogicalSimulator().task(main)except BaseException as e:    print("Error during kernel definition or task creation:", e)
Error during kernel definition or task creation:Validation failed with 3 violation(s):
Gemini Logical Validation: - Qubit allocations exceeded 10. (inlined from 'qalloc' called at /tmp/ipykernel_5217/1299499624.py:4; decorate the calling kernel with `aggressive_unroll=True` to inline and unroll the call, or with `verify=False` to skip these checks) File"/codebuild/output/src1944220347/src/bloqade-website/emitters/notebooks/.venv/lib/python3.12/site-packages/bloqade/qubit/stdlib/_new.py", line 32, col 15 │ │ def _new(qid: int) -> qubit.Qubit: 32│ return qubit.new() │ ^^^^^^^^^^^ │ │ return ilist.map(_new, ilist.range(n_qubits))
- Qubit allocations exceeded 10. (inlined from 'qalloc' called at /tmp/ipykernel_5217/1299499624.py:4; decorate the calling kernel with `aggressive_unroll=True` to inline and unroll the call, or with `verify=False` to skip these checks) File"/codebuild/output/src1944220347/src/bloqade-website/emitters/notebooks/.venv/lib/python3.12/site-packages/bloqade/qubit/stdlib/_new.py", line 32, col 15 │ │ def _new(qid: int) -> qubit.Qubit: 32│ return qubit.new() │ ^^^^^^^^^^^ │ │ return ilist.map(_new, ilist.range(n_qubits))
- kernel allocates 12 qubits, exceeding the maximum of 10 File "/tmp/ipykernel_5217/1299499624.py", line 8, col 43 │ squin.cx(reg[0], reg[1]) │ 8│ return logical.default_post_processing(reg) │ ^^^Repeated non-Clifford rotations
try:    @logical.kernel(aggressive_unroll=True, verify=True)    def main():        reg = squin.qalloc(10)        squin.t(reg[0])        squin.t(reg[0])        squin.cx(reg[0], reg[1])
        return logical.default_post_processing(reg)
    task = GeminiLogicalSimulator().task(main)except BaseException as e:    print("Error during kernel definition or task creation:", e)
Error during kernel definition or task creation:Validation failed with 1 violation(s):
Gemini Logical Validation: - Non-clifford gate t can only be used for initial state preparation, i.e. as the first gate! (inlined from 't' called at /tmp/ipykernel_5217/4047127049.py:5; decorate the calling kernel with `aggressive_unroll=True` to inline and unroll the call, or with `verify=False` to skip these checks) File"/codebuild/output/src1944220347/src/bloqade-website/emitters/notebooks/.venv/lib/python3.12/site-packages/bloqade/squin/stdlib/broadcast/gate.py", line 71, col 11 │ qubits (ilist.IList[Qubit, Any]): Target qubits. │ """ 71│ gate.t(qubits, adjoint=False) │ ^^^^^^Non-Clifford rotation not as the first gate (This is the same validation error)
try:    @logical.kernel(aggressive_unroll=True, verify=True)    def main():        reg = squin.qalloc(10)        squin.h(reg[0])        squin.cx(reg[0], reg[1])        squin.t(reg[0])
        return logical.default_post_processing(reg)
    task = GeminiLogicalSimulator().task(main)except BaseException as e:    print("Error during kernel definition or task creation:", e)
Error during kernel definition or task creation:Validation failed with 1 violation(s):
Gemini Logical Validation: - Non-clifford gate t can only be used for initial state preparation, i.e. as the first gate! (inlined from 't' called at /tmp/ipykernel_5217/818871875.py:7; decorate the calling kernel with `aggressive_unroll=True` to inline and unroll the call, or with `verify=False` to skip these checks) File"/codebuild/output/src1944220347/src/bloqade-website/emitters/notebooks/.venv/lib/python3.12/site-packages/bloqade/squin/stdlib/broadcast/gate.py", line 71, col 11 │ qubits (ilist.IList[Qubit, Any]): Target qubits. │ """ 71│ gate.t(qubits, adjoint=False) │ ^^^^^^Explicitly annotate parallelism
Section titled “Explicitly annotate parallelism”If parallelism is not annotated, the program will implement each two qubit gate sequentially. We currently do not have any auto-paralellization passes.
def logical_kernel_wrapper(kernel:Method[[], ilist.IList[types.Qubit, Any]]) -> Method:    """    A helper function that wraps a kernel that returns a qubit register that has    had some computation performed on it and wraps it in a logical kernel.    """    @logical.kernel(aggressive_unroll=True, verify=True)    def terminal_main():        reg = kernel()
logical.default_post_processing(reg) return terminal_main@squin.kerneldef unparallelized_main()->ilist.IList[types.Qubit, Any]: """ A kernel that annotates no parallelism, even though they exist """ reg = squin.qalloc(4) squin.cx(reg[0], reg[1]) squin.cx(reg[2], reg[3]) return reg
@squin.kerneldef parallelized_main()->ilist.IList[types.Qubit, Any]: """ An equivalent kernel to the above, but with parallelism annotated via broadcast operations. """ reg = squin.qalloc(4) squin.broadcast.cx(ilist.IList([reg[0], reg[2]]), ilist.IList([reg[1], reg[3]])) return reg
@squin.kerneldef conflicted_parallelized_main()->ilist.IList[types.Qubit, Any]: """ A kernel where parallelism is annotated, but the moves cannot be done all at once due to AOD constraints. """ reg = squin.qalloc(4) squin.broadcast.cx(ilist.IList([reg[0], reg[1]]), ilist.IList([reg[3], reg[2]])) return reg
unparallelized_main = logical_kernel_wrapper(unparallelized_main)parallelized_main = logical_kernel_wrapper(parallelized_main)conflicted_parallelized_main = logical_kernel_wrapper(conflicted_parallelized_main)
task_unparallelized = GeminiLogicalSimulator().task(unparallelized_main)task_parallelized = GeminiLogicalSimulator().task(parallelized_main)task_conflicted_parallelized = GeminiLogicalSimulator().task(conflicted_parallelized_main)To illustrate the impact of noise on the different types of kernels above, we print a “fidelity” value, which is the probability that all qubits experience no gate errors.
The unparallelized circuit sequentially does the two gates with two sets of moves.
_, fidelity = task_unparallelized.fidelity_bounds()print("Fidelity bounds for unparallelized main:", fidelity)task_unparallelized.tsim_circuit.diagram(height=task_unparallelized.tsim_circuit.num_qubits*10)Fidelity bounds for unparallelized main: 0.5160764040517819
The parallelized circuit does a parallel move and implements both gates at the same time. Because only one CZ pulse is applied, the fidelity is higher.
_, f = task_parallelized.fidelity_bounds()print("Fidelity bounds for parallelized main:", f)task_parallelized.tsim_circuit.diagram(height=task_parallelized.tsim_circuit.num_qubits*10)Fidelity bounds for parallelized main: 0.637219665010538
The parallelized but conflicted circuit implements two sequential moves and then does both gates at the same time. As a result, the fidelity is lower.
_, f = task_conflicted_parallelized.fidelity_bounds()print("Fidelity bounds for conflicted parallelized main:", f)task_conflicted_parallelized.tsim_circuit.diagram(height=task_conflicted_parallelized.tsim_circuit.num_qubits*10)Fidelity bounds for conflicted parallelized main: 0.46021626648276515
As we can see from the above examples, noise is added to the circuit based on the moves required for the circuit as well as the number of CZ pulses.